The public release of weights and technical specifications for DeepSeek-V3 and DeepSeek-R1 has created an irreversible watershed moment across the global artificial intelligence landscape: proving that doctoral-level frontier reasoning models can be developed and operated at a minute fraction of legacy compute budgets.
1. The 671B Mixture-of-Experts (MoE) Topology with Fine-Grained Sparsity
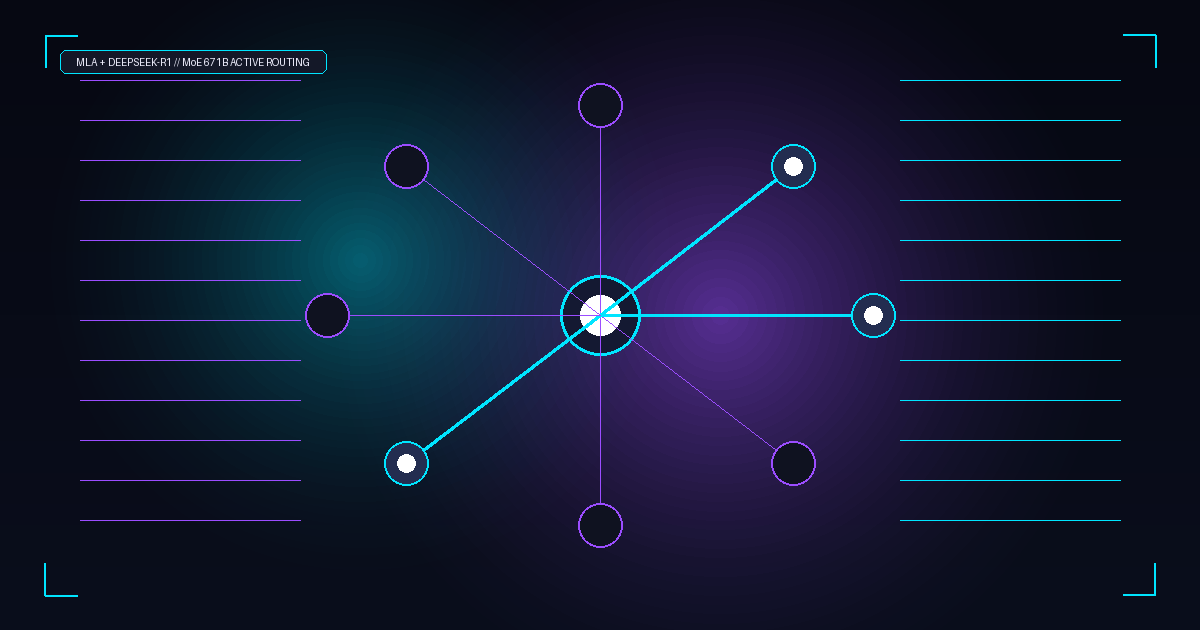
Unlike legacy dense transformers where every forward token pass mobilizes 100% of network parameters, DeepSeek-V3 deploys an ultra-sparse architecture consisting of 671 billion total parameters, dynamically activating a compact subset of 37 billion parameters per token.
This dynamic routing is governed by an innovative Auxiliary-Loss-Free Load Balancing algorithm. By eliminating traditional auxiliary loss penalties that historically constrained linguistic expressiveness by artificially forcing uniform expert dispatch, the model allows specialized experts to achieve peak contextual mastery without inducing GPU core starvation.
KV Cache Memory Compression: The implementation of Multi-Head Latent Attention (MLA) compresses Key-Value projections into a low-rank latent subspace, diminishing total KV Cache overhead by 93.3% compared to traditional Multi-Head Attention (MHA). This unlocks cost-effective 128k-token enterprise context execution on commodity clusters.
2. Pure Reinforcement Learning: GRPO Without Dedicated Critic Models
DeepSeek-R1's primary theoretical milestone is the emergence of meta-cognitive reasoning patterns—spontaneous self-reflection, mathematical backtracking, and verification loops—through Pure Reinforcement Learning, completely bypassing initial massive supervised instruction tuning.
Rather than relying on classic Proximal Policy Optimization (PPO), which demands concurrent memory allocation for actor, critic, and reward networks, the researchers introduced Group Relative Policy Optimization (GRPO). GRPO samples a candidate cluster of generations per input prompt and normalizes relative reward baselines strictly within the group, significantly reducing memory consumption and stabilizing high-variance mathematical optimization.
3. Enterprise Sovereignty: Deploying Frontier Reasoning On-Premise
For enterprises within finance, defense, life sciences, and critical public infrastructure, the availability of open weights such as DeepSeek-R1 and its distilled siblings (1.5B to 70B parameter models) eliminates architectural dependency on closed hyper-scaler APIs.
At Better2Better, we engineer enterprise-grade inference pipelines leveraging vLLM and SGLang with native FP8 quantization support. This enables organizations to audit proprietary code, process highly sensitive customer dossiers, and automate compliance audits with absolute zero-trust data custody.
4. Architectural Benchmark Matrix
| Metric / Architectural Trait | Legacy Dense (175B) | Proprietary Closed MoE | DeepSeek-V3 / R1 (Open) |
|---|---|---|---|
| Active Parameters | 175B (100%) | Est. ~50B | 37B (Sparse) |
| KV Cache Footprint | Extremely High (MHA) | Moderate (GQA) | Ultra-Low (Latent MLA) |
| Reasoning Alignment | SFT + PPO with Critic | Closed Instruction Tuning | Pure GRPO + Open Distillations |
| Deployment Sovereignty | Private Cloud Only | Restricted API Only | Air-Gapped / Bare-Metal / Sovereign Cloud |
5. Academic Citations & Technical Bibliography
Peer-Reviewed Research & Foundation Papers:
- DeepSeek-AI Team (2025). DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. arXiv:2501.12948 [cs.CL].
- DeepSeek-AI Team (2024). DeepSeek-V3 Technical Report: Architecture, Training and Alignment. arXiv:2412.19437 [cs.CL].
- Shao, Z., Wang, P., Zhu, Q., et al. (2024). DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. arXiv:2402.03300.
- Schulman, J., Wolski, F., Dhariwal, P., et al. (2017). Proximal Policy Optimization Algorithms. arXiv:1707.06347.
Enterprise AI Security Guarantees & Cryptographic Code Audits
Deploying autonomous agent swarms without hardened defense layers is the single highest operational risk in modern computing. At Better2Better, our dedicated team led by Felipe Siqueira and Dr. Helena Vance performs deep architectural code audits, neutralizing prompt injections, securing vector memories in gVisor sandboxes, and orchestrating execution across encrypted hardware enclaves.
What can we build for you today?
Enjoyed this deep dive? Deploy enterprise autonomous AI agent swarms with guaranteed security hardening clicking here!
🤖 Deploy Autonomous AI Agents via WhatsAppEnterprise AI Security Guarantees & Cryptographic Code Audits
Deploying autonomous agent swarms without hardened defense layers is the single highest operational risk in modern computing. At Better2Better, our dedicated team led by Felipe Siqueira and Dr. Helena Vance performs deep architectural code audits, neutralizing prompt injections, securing vector memories in gVisor sandboxes, and orchestrating execution across encrypted hardware enclaves.
What can we build for you today?
Enjoyed this deep dive? Deploy enterprise autonomous AI agent swarms with guaranteed security hardening clicking here!
🤖 Deploy Autonomous AI Agents via WhatsApp