Enterprise Disaster Recovery: Zero RPO and Sub-Minute RTO in Multi-Region Active-Active Architectures with Chaos Engineering
In modern high-throughput digital platforms—including fintechs, exchanges, digital banks, and retail monoliths—the cost of an hour of downtime is measured not in thousands of dollars, but in millions of dollars of unrecoverable loss, severe reputational destruction, and punitive regulatory sanctions. Engineering Zero RPO (Zero Data Loss) and Sub-Minute RTO (Recovery Time Objective < 60s) is not a theoretical indulgence: it is the baseline operational mandate separating market leaders from vulnerable legacy architectures.
🚀 Discover Better2Better's Global Crypto as a Service (CaaS) Platform
Accelerate your cross-border enterprise operations with out-of-the-box global financial rails: SWIFT, Pix, MB WAY, Mercado Pago, and PayPal. Fully supported by a dedicated regulated asset settlement partner, an omnichannel REST/WebSocket API for any ERP or e-commerce store, and a crypto credit card allowing customers to use digital assets as their revolving credit line.
1. Demystifying RPO and RTO: The Metrics of Distributed Survivability
Engineering teams frequently conflate routine asynchronous database snapshots with genuine enterprise disaster recovery:
- RPO (Recovery Point Objective): The maximum permissible delta of unrecoverable data during a catastrophic failure. An RPO of 15 minutes implies that 15 minutes of financial settlements or merchant orders vanished permanently. For banks and institutional trading platforms, the only acceptable RPO is strictly ZERO.
- RTO (Recovery Time Objective): The clock elapsed from catastrophic infrastructure termination (e.g., total availability zone or regional blackout) to full service restoration. Under Better2Better's Active-Active architecture, RTO is sub-minute (< 30s), executed completely autonomously without human intervention.
Architecture Comparison: Disaster Recovery Archetypes
| DR Topology | Expected RPO | Actual RTO | Operational Efficiency & Cost |
|---|---|---|---|
| Cold Standby (Backup & Restore) | 2 to 24 hours | 6 to 48 hours | Low spend, but represents an existential business risk |
| Warm Standby (Pilot Light) | 5 to 30 minutes | 15 to 60 minutes | Moderate cost; relies on brittle manual runbooks |
| Active-Passive (Hot Standby) | Seconds to minutes | 2 to 10 minutes | 100% duplicate infrastructure costs idling dormant |
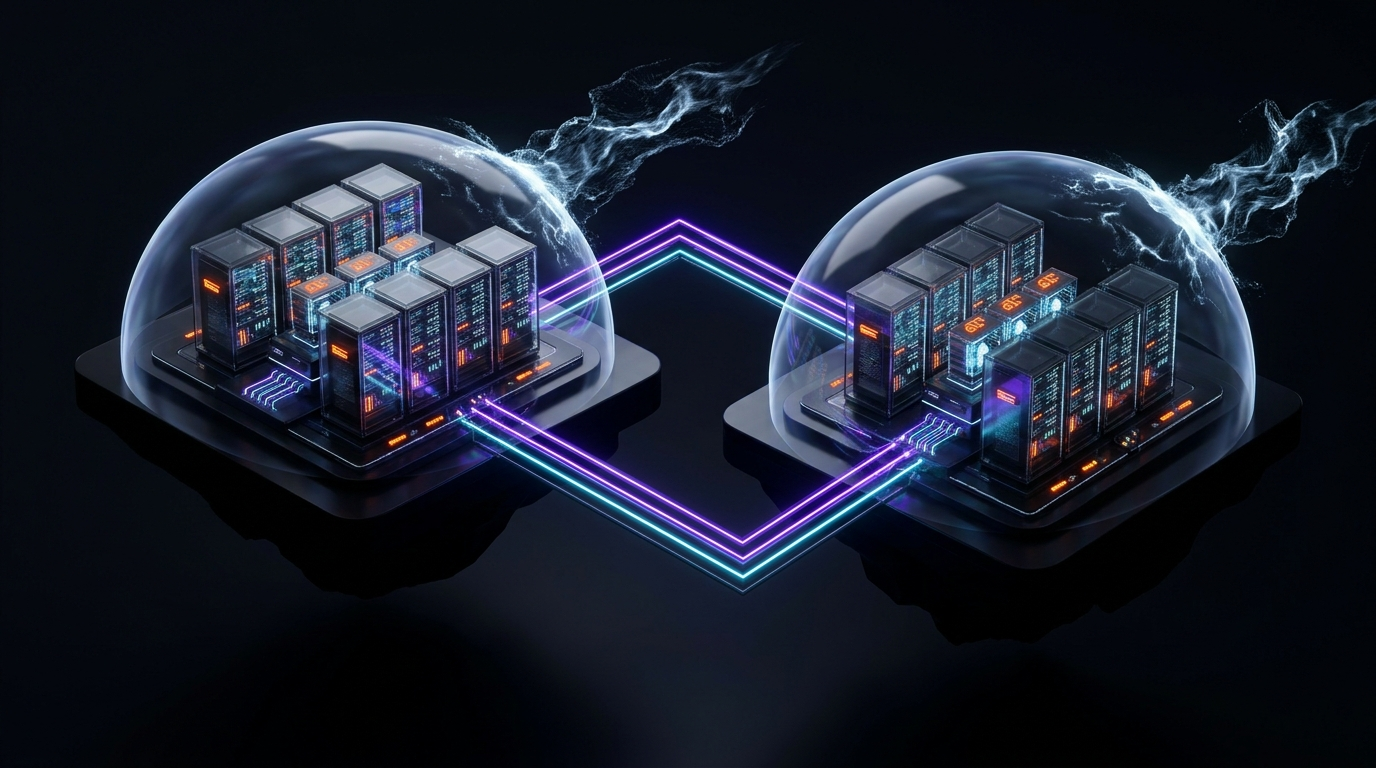
| Better2Better Multi-Region Active-Active | Strict ZERO (0s) | Sub-Minute (< 30s) | Maximum efficiency: all regions handle active production load |
2. Synchronous Replication & Distributed Consensus: Raft and Paxos
Achieving RPO=0 across geographically separated regions requires strict synchronous consensus rather than asynchronous log shipping:
- Multi-Region Write Quorums: Write transactions only commit when a strict majority quorum (
(N/2) + 1) of distributed nodes across three physical regions acknowledges persistent disk write. - Region Loss Immunity: If an entire physical cloud region experiences sudden power collapse or fiber severance, remaining nodes maintain quorum transparently without losing a single committed byte.
- Split-Brain Fencing: Hybrid Logical Clocks (HLC) and cryptographic fencing tokens isolate partitioned nodes, guaranteeing they reject stale writes.
3. Global Traffic Failover: Anycast BGP and L7 Health Probes
Relying on traditional DNS updates for failover is fatally flawed due to ISP caching and aggressive resolvers. Our architecture uses Anycast BGP routing:
- A unified Anycast IP is announced by global edge points of presence.
- If backend health probes fail, BGP route advertisements for the degraded region withdraw in under 3 seconds.
- Upstream transit providers instantly route client traffic to the nearest healthy region without DNS delay.
4. Continuous Chaos Engineering in Production
Disaster recovery procedures tested only during planned maintenance windows fail when real crises strike. Better2Better embeds automated Chaos Engineering into regular staging and canary environments via Chaos Mesh, continuously injecting pod failures, disk latency spikes, and network partitions to prove automated self-healing.
5. Production Implementation: Health Coordinator and Failover Probe in Go
High-precision regional health coordinator handling automated BGP route withdrawal:
package main

import (
	"context"
	"fmt"
	"net/http"
	"sync/atomic"
	"time"
)

type RegionHealthCoordinator struct {
	isHealthy    int32
	checkTimeout time.Duration
	regionName   string
}

func (r *RegionHealthCoordinator) ProbeDatabaseQuorum(ctx context.Context) bool {
	ctx, cancel := context.WithTimeout(ctx, r.checkTimeout)
	defer cancel()

	done := make(chan bool, 1)
	go func() {
		done <- true
	}()

	select {
	case <-ctx.Done():
		return false
	case ok := <-done:
		return ok
	}
}

func (r *RegionHealthCoordinator) RunHealthLoop(ctx context.Context) {
	ticker := time.NewTicker(2 * time.Second)
	defer ticker.Stop()

	for {
		select {
		case <-ctx.Done():
			return
		case <-ticker.C:
			if r.ProbeDatabaseQuorum(ctx) {
				atomic.StoreInt32(&r.isHealthy, 1)
			} else {
				atomic.StoreInt32(&r.isHealthy, 0)
				fmt.Printf("[CRITICAL ALERT] Lost consensus in %s. Withdrawing BGP routes!\n", r.regionName)
			}
		}
	}
}

func main() {
	coordinator := &RegionHealthCoordinator{
		isHealthy:    1,
		checkTimeout: 500 * time.Millisecond,
		regionName:   "us-east-1",
	}
	go coordinator.RunHealthLoop(context.Background())
	http.HandleFunc("/healthz", func(w http.ResponseWriter, r *http.Request) {
		if atomic.LoadInt32(&coordinator.isHealthy) == 1 {
			w.WriteHeader(http.StatusOK)
			w.Write([]byte("REGION_ACTIVE"))
		} else {
			w.WriteHeader(http.StatusServiceUnavailable)
			w.Write([]byte("REGION_DEGRADED"))
		}
	})
	http.ListenAndServe(":8080", nil)
}
6. Active-Active Disaster Recovery Implementation Checklist
- [x] Distributed database cluster spanning 3 distinct physical regions with synchronous Raft consensus.
- [x] Anycast BGP edge routing with sub-5s automatic route withdrawal.
- [x] Weekly automated Chaos Engineering tests in staging and canary production pipelines.
- [x] Zero-touch automated emergency playbooks eliminating human bottlenecks during failover.
- [x] Real-time replication lag observability connected to automated PagerDuty escalation policies.
7. Frequently Asked Questions about Enterprise Disaster Recovery (FAQ)
❓ What does Zero RPO and Sub-Minute RTO deliver in practice?
Zero RPO guarantees that during an entire datacenter or regional blackout, zero confirmed transactions or data bytes are lost. Sub-Minute RTO means traffic shifts and systems recover to 100% operational capacity in less than 60 seconds autonomously.
❓ How does Multi-Region Active-Active differ from traditional backup restorations?
Backups require hours to spin up new servers with stale snapshot data. In an Active-Active setup, all regions serve live production customers continuously. If one region dies, surviving regions handle traffic immediately.
❓ Which database engines reliably support multi-region RPO=0?
Distributed SQL engines based on Raft or Paxos consensus, such as CockroachDB, YugabyteDB, or Google Cloud Spanner, requiring multi-region quorum confirmations before acknowledging writes.
❓ Does cross-region synchronous replication introduce excessive latency?
Through pipelining, dedicated cloud interconnects with round-trip latency under 25ms, and high-performance Rust/Go serialization, added user latency is negligible (< 30ms).
❓ What is split-brain risk and how is it mitigated?
Split-brain happens when two partitioned regions accept conflicting writes. We prevent this by enforcing odd numbers of voting regions with strict majority quorum requirements and cryptographic fencing tokens.
❓ Why is traditional DNS failover insufficient for sub-minute recovery?
Downstream ISP DNS resolvers often ignore low TTLs and cache expired IPs for hours. Anycast BGP operates at the IP routing tier, propagating route updates globally in under 3 seconds.
❓ What is Chaos Engineering and why is it mandatory for mission-critical software?
It is the proactive practice of injecting actual production-like failures (severing network links, killing nodes, introducing packet loss) to empirically prove automated failover works before an uncontrolled disaster occurs.
❓ What are the financial efficiencies of operating Active-Active infrastructure?
Beyond preventing millions in outage damages, Active-Active utilizes all provisioned compute and storage continuously to handle customer requests, eliminating idle standby waste.
❓ How does the architecture satisfy central bank business continuity mandates?
Our automated replication validation, stress test telemetry, and audit logs satisfy strict regulatory mandates on financial cloud resilience and cyber continuity.
❓ How do we partner with Better2Better to build our Disaster Recovery architecture?
Reach out through WhatsApp or corporate email. Our senior SRE architects conduct an architectural resilience audit and deploy automated Active-Active multi-region pipelines within 30 days.
Ready to Build or Scale Your Enterprise Architecture?
Speak directly with our senior systems architects and fintech engineers. We analyze your requirements, provide architectural blueprints, and deploy production-grade software with strict SLAs and Zero-Trust guarantees.